

Lazarus-Free-Pascal-Local-LLM-wrapper

Native Lazarus (Free Pascal) Local LLM wrapper demo supporting Ollama and LM Studio.
- Active · last change 5-6-2026
- ★ 10 on GitHub
README
Lazarus Local LLM Wrapper Demo
A lightweight Free Pascal / Lazarus demo showing how to connect a native desktop application to local Large Language Models (LLMs) such as Ollama and LM Studio.
This project demonstrates that modern AI integrations can be implemented entirely in Lazarus (Object Pascal) — without Python, Node.js, or external runtimes.
✨ Features
- ✅ Native Lazarus / Free Pascal implementation
- ✅ Supports Ollama (
/api/chat) - ✅ Supports LM Studio (OpenAI-compatible API)
- ✅ Background threading (non-blocking UI)
- ✅ Multi-turn conversation history
- ✅ Cancel request support (non-blocking)
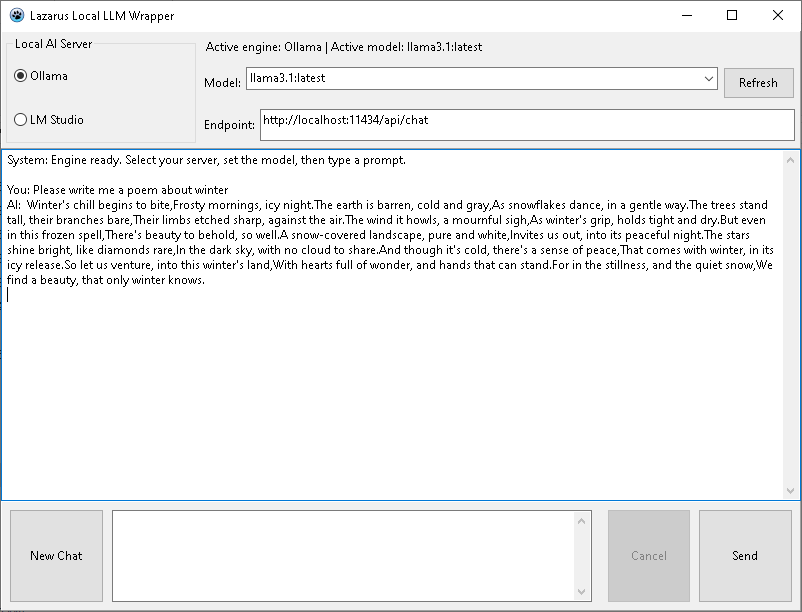
- ✅ Simple and clean demo UI
Screenshot
🧠 Supported Backends
1. Ollama
- Endpoint:
http://localhost:11434/api/chat - Model example:
llama3.1,mistral, etc.
2. LM Studio
- Endpoint:
http://localhost:1234/v1/chat/completions - OpenAI-compatible API
🚀 Getting Started
1. Install Lazarus
Download and install:
2. Setup Ollama
Install Ollama:
Pull a model:
ollama pull llama3.1Start the server:
ollama serveDefault API:
http://localhost:114343. Setup LM Studio (Optional)
Download:
Steps:
- Load any model
- Start local server
- Default endpoint:
http://localhost:12344. Open the Project
- Open Lazarus IDE
- Load project file (
.lpror.lpi) - Build and Run
🖥️ Usage
- Select backend (Ollama / LM Studio)
- Enter model name
- Type a prompt
- Click Send
- View response in the memo panel
⚠️ Important Notes
Cancel Behavior
The Cancel button does NOT immediately abort the HTTP request.
Instead:
- It marks the request as cancelled
- The response is ignored when it returns
This is sufficient for demo purposes but not a full cancellation mechanism.
Not Production Ready
This project is a:
⚠️ Proof-of-Concept / Demo
It is not yet suitable for production use.
Missing features include:
- Streaming responses
- Robust cancellation (socket-level)
- Advanced error handling
- Context window management
- Authentication / API key support
🧱 Architecture Overview
LocalLLM.pas→ Core wrapper componentTLocalLLM→ Handles API requests and historyTLocalLLMThread→ Background executionMainUnit.pas→ Demo UI
💡 Purpose of This Project
This demo exists to show:
You can build modern AI-powered applications using Lazarus / Free Pascal
without relying on:
- Python ecosystems
- JavaScript frameworks
- Cloud-based APIs
🛣️ Future Improvements
- Streaming token support
- Multi-model orchestration
- Plugin/tool system
- Better cancellation (interrupt HTTP)
- History summarization
- GPU/quantization controls
📄 License
MIT License (recommended) — feel free to modify.
🤝 Contributions
Contributions are welcome! Feel free to fork, improve, or extend this into a full local AI runtime.
⭐ If you find this useful
Give it a star on GitHub — it helps others discover Lazarus-based AI projects 👍