
LCL Unicode Support/zh CN: what changed
Revision 2 to 3. Removed lines have a minus sign; added lines have a plus sign.
| Old | New | Line | |
|---|---|---|---|
| 1 | 1 | ## 介绍 | |
| 2 | 2 | ||
| 3 | 3 | 自0.9.25版本开始,Lazarus已经完全支持所有平台上的Unicode编码,只有GTK1除外。本页包含辣子用户的使用说明、辣子对Unicode的计划,相关的基本概念以及目前辣子对于Unicode已有实现的细节。 | |
| 4 | 4 | ||
| 5 | 5 | (译者注:本文基本是对英文版的翻译,但是因为辣子对于Unicode的支持一直都在进展中,所以本文可能在你看到时已经过时) | |
| 6 | 6 | ||
| 7 | 7 | ## 辣子用户的操作指南 | |
| 8 | 8 | ||
| 9 | 9 | 尽管辣子拥有一套Unicode的控件集,但应被指出的是,不是所有的东西都是Unicode的。开发人员应自己负责掌控自己的字符串是什么编码,并且在使用了不同编码方式的库之间做出正确的编码转换。 | |
| 10 | 10 | ||
| 11 | 11 | 通常,每一个库自己会保持一致的字符编码(库指的是dll或者辣子的package)。一般要么是Unicode(对于Lazarus一直是UTF-8),要么是Ansi(系统编码的意思,可能是utf-8可能不是)。FPC2.4附带的RTL和FCL都使用Ansi。目前看来FPC2.5.X也是这样。 | |
| 12 | 12 | ||
| 13 | 13 | 你能用System单元中的两个函数来转换这两种编码的字符串,UTF8ToAnsi和AnsiToUTF8。 FileUtil单元中提供的UTF8ToSys和SysToUTF8也提供类似功能,不过它们更灵活一些,使用它们就得多写一些代码。 | |
| 14 | 14 | ||
| 15 | 15 | ### FPC不使用Unicode | |
| 16 | 16 | ||
| 17 | 17 | 目前版本(截止到现在的FPC2.5.X)的Free Pascal的RTL(Runtime Library)和Free Pascal的FCL(Free Component Library)都是Ansi的,在和Unicode的库交互时注意转换。 | |
| 18 | 18 | ||
| 19 | 19 | ### ANSI和Unicode互相转换的例子 | |
| 20 | 20 | ||
| 21 | 21 | 话说你从TEdit得到一个字符串,然后你想把它当参数传给某些个RTL中文件处理相关的函数: | |
| 22 | 22 | ||
| 23 | 23 | ``` pascal | |
| 24 | 24 | var | |
| 25 | 25 | MyString: string; // utf-8 encoded | |
| 26 | 26 | begin | |
| 27 | 27 | MyString := MyTEdit.Text; | |
| 28 | 28 | SomeRTLRoutine(UTF8ToAnsi(MyString)); | |
| 29 | 29 | end; | |
| 30 | 30 | ``` | |
| 31 | 31 | ||
| 32 | 32 | 还有反向的: | |
| 33 | 33 | ||
| 34 | 34 | ``` pascal | |
| 35 | 35 | var | |
| 36 | 36 | MyString: string; // ansi encoded | |
| 37 | 37 | begin | |
| 38 | 38 | MyString := SomeRTLRoutine; | |
| 39 | 39 | MyTEdit.Text := AnsiToUTF8(MyString); | |
| 40 | 40 | end; | |
| 41 | 41 | ``` | |
| 42 | 42 | ||
| 43 | 43 | **注意**:UTF8ToAnsi如果探测到传入的UTF-8字符串中包含非法字符,会返回一个空string。 **注意**:在Linux,BSD和Mac OS X下,AnsiToUTF8和UTF8ToAnsi需要一个WideString Manager才能使用。这种情况下,你可以转而使用FileUtil单元提供的SysToUTF8和UTF8ToSys,或者通过把cwstring单元放到你的程序的uses第一个单元来添加这个WideString Manager。 | |
| 44 | 44 | ||
| 45 | 45 | ### 应付UTF8 String和字符 | |
| 46 | 46 | ||
| 47 | 47 | 在辣子版本0.9.30的时候,UTF8的处理函数们还都在LCL的LCLProc单元中。在版本0.9.31+起,LCLProc中的的这些函数为了兼容老代码依然保留,但是真正的处理代码(LCLProc中的这些函数只剩下声明了)都转移到了lazutils这个package的lazutf8单元中了。 | |
| 48 | 48 | ||
| 49 | 49 | 如果你要操作的字符串是UTF8的,以后应当尽量使用lazutf8单元而不是FPC附带的SysUtils单元来处理,毕竟SysUtils到现在也没准备好支持Unicode,但是lazutf8可以。lazutf8重新实现的SysUtils中的字符串处理函数,一般都是在原函数(SysUtils中的)的名字前面加了前缀UTF8。 | |
| 50 | 50 | ||
| 51 | 51 | 另外要说明的是,在Unicode的语境下,用char为单位,把一个string当成一个char array来遍历是不行的。不只是UTF8会这样,目前Unicode的常见编码(UTF8、UTF16)中,一个字符用多少个char来编码都是不定的。如果你想遍历一个UTF-8 string中的所有字符,一般有两种办法: | |
| 52 | 52 | ||
| 53 | 53 | - 以byte为单位遍历,如果你只是想处理这个UTF-8 string中的ASCII字符的话。例如在解析一个xml的时候。 | |
| 54 | 54 | - 以charactor为单位,这在synedit之类的可视化控件中很有用。例如你想知道某个控件中显示的第三个字符是个啥。(译者注:参看下文“遍历UTF8字符串”) | |
| 55 | 55 | ||
| 56 | 56 | #### 查找子串 | |
| 57 | 57 | ||
| 58 | 58 | 因为UTF8编码本身的特点(译注:兼容ASCII),你可以用普通的字符串处理函数来查找: | |
| 59 | 59 | ||
| 60 | 60 | ``` pascal | |
| 61 | 61 | uses lazutf8; // LCLProc for Lazarus 0.9.30 or inferior | |
| 62 | 62 | ... | |
| 63 | 63 | procedure Where(SearchFor, aText: string); | |
| 64 | 64 | var | |
| 65 | 65 | BytePos: LongInt; | |
| 66 | 66 | CharacterPos: LongInt; | |
| 67 | 67 | begin | |
| 68 | 68 | BytePos:=Pos(SearchFor,aText); | |
| 69 | 69 | CharacterPos:=UTF8Length(PChar(aText),BytePos-1); | |
| 70 | 70 | writeln('The substring "',SearchFor,'" is in the text "',aText,'"', | |
| 71 | 71 | ' at byte position ',BytePos,' and at character position ',CharacterPos); | |
| 72 | 72 | end; | |
| 73 | 73 | ``` | |
| 74 | 74 | ||
| 75 | 75 | #### 遍历UTF8字符串 | |
| 76 | 76 | ||
| 77 | 77 | 注:某个Unicode字符在UTF8中不一定需要几个byte(最多三个)来编码。 下面代码按照charactor遍历了一个UTF8字符串: | |
| 78 | 78 | ||
| 79 | 79 | ``` pascal | |
| 80 | 80 | uses lazutf8; // LCLProc for Lazarus 0.9.30 or inferior | |
| 81 | 81 | ... | |
| 82 | 82 | procedure DoSomethingWithString(AnUTF8String: string); | |
| 83 | 83 | var | |
| 84 | 84 | p: PChar; | |
| 85 | 85 | CharLen: integer; | |
| 86 | 86 | FirstByte, SecondByte, ThirdByte: Char; | |
| 87 | 87 | begin | |
| 88 | 88 | p:=PChar(AnUTF8String); | |
| 89 | 89 | repeat | |
| 90 | 90 | CharLen := UTF8CharacterLength(p); | |
| 91 | 91 | ||
| 92 | 92 | // here you have a pointer to the char and it's length | |
| 93 | 93 | // You can access the bytes of the UTF-8 Char like this: | |
| 94 | 94 | if CharLen >= 1 then FirstByte := P[0]; | |
| 95 | 95 | if CharLen >= 2 then SecondByte := P[1]; | |
| 96 | 96 | if CharLen >= 3 then ThirdByte := P[2]; | |
| 97 | 97 | ||
| 98 | 98 | inc(p,CharLen); | |
| 99 | 99 | until (CharLen=0) or (p^ = #0); | |
| 100 | 100 | end; | |
| 101 | 101 | ``` | |
| 102 | 102 | ||
| 103 | 103 | #### 访问UTF8字符串中的第N个字符 | |
| 104 | 104 | ||
| 105 | 105 | lazutf8提供了一个函数(译注:因为UTF8编码本身的特点,这个函数本身应该也是遍历实现的): | |
| 106 | 106 | ||
| 107 | 107 | ``` pascal | |
| 108 | 108 | uses lazutf8; // LCLProc for Lazarus 0.9.30 or inferior | |
| 109 | 109 | ... | |
| 110 | 110 | var | |
| 111 | 111 | AnUTF8String, NthChar: string; | |
| 112 | 112 | begin | |
| 113 | 113 | NthChar := UTF8Copy(AnUTF8String, N, 1); | |
| 114 | 114 | ``` | |
| 115 | 115 | ||
| 116 | 116 | #### 使用UTF8CharactorToUnicode来得到每个字符的codepoint | |
| 117 | 117 | ||
| 118 | 118 | 以下演示如何得到一个UTF8字符串中每个字符的32位整数大小的codepoint: | |
| 119 | 119 | ||
| 120 | 120 | ``` pascal | |
| 121 | 121 | uses lazutf8; // LCLProc for Lazarus 0.9.30 or inferior | |
| 122 | 122 | ... | |
| 123 | 123 | procedure IterateUTF8Characters(const AnUTF8String: string); | |
| 124 | 124 | var | |
| 125 | 125 | p: PChar; | |
| 126 | 126 | unicode: Cardinal; | |
| 127 | 127 | CharLen: integer; | |
| 128 | 128 | begin | |
| 129 | 129 | p:=PChar(AnUTF8String); | |
| 130 | 130 | repeat | |
| 131 | 131 | unicode:=UTF8CharacterToUnicode(p,CharLen); | |
| 132 | 132 | writeln('Unicode=',unicode); | |
| 133 | 133 | inc(p,CharLen); | |
| 134 | 134 | until (CharLen=0) or (unicode=0); | |
| 135 | 135 | end; | |
| 136 | 136 | ``` | |
| 137 | 137 | ||
| 138 | 138 | #### UTF8版本的Copy, Length, LowerCase等等 | |
| 139 | 139 | ||
| 140 | 140 | 你能想到的,lazutf8基本都提供了(前面也说过,0.9.30及以前版本使用LCLProc单元而不是新的lazutf8单元)。下面是lazutf8.pas中的一个片段: | |
| 141 | 141 | ||
| 142 | 142 | ``` pascal | |
| 143 | 143 | function UTF8CharacterLength(p: PChar): integer; | |
| 144 | 144 | function UTF8Length(const s: string): PtrInt; | |
| 145 | 145 | function UTF8Length(p: PChar; ByteCount: PtrInt): PtrInt; | |
| 146 | 146 | function UTF8CharacterToUnicode(p: PChar; out CharLen: integer): Cardinal; | |
| 147 | 147 | function UnicodeToUTF8(u: cardinal; Buf: PChar): integer; inline; | |
| 148 | 148 | function UnicodeToUTF8SkipErrors(u: cardinal; Buf: PChar): integer; | |
| 149 | 149 | function UnicodeToUTF8(u: cardinal): shortstring; inline; | |
| 150 | 150 | function UTF8ToDoubleByteString(const s: string): string; | |
| 151 | 151 | function UTF8ToDoubleByte(UTF8Str: PChar; Len: PtrInt; DBStr: PByte): PtrInt; | |
| 152 | 152 | function UTF8FindNearestCharStart(UTF8Str: PChar; Len: integer; | |
| 153 | 153 | BytePos: integer): integer; | |
| 154 | 154 | // find the n-th UTF8 character, ignoring BIDI | |
| 155 | 155 | function UTF8CharStart(UTF8Str: PChar; Len, CharIndex: PtrInt): PChar; | |
| 156 | 156 | // find the byte index of the n-th UTF8 character, ignoring BIDI (byte len of substr) | |
| 157 | 157 | function UTF8CharToByteIndex(UTF8Str: PChar; Len, CharIndex: PtrInt): PtrInt; | |
| 158 | 158 | procedure UTF8FixBroken(P: PChar); | |
| 159 | 159 | function UTF8CharacterStrictLength(P: PChar): integer; | |
| 160 | 160 | function UTF8CStringToUTF8String(SourceStart: PChar; SourceLen: PtrInt) : string; | |
| 161 | 161 | function UTF8Pos(const SearchForText, SearchInText: string): PtrInt; | |
| 162 | 162 | function UTF8Copy(const s: string; StartCharIndex, CharCount: PtrInt): string; | |
| 163 | 163 | procedure UTF8Delete(var s: String; StartCharIndex, CharCount: PtrInt); | |
| 164 | 164 | procedure UTF8Insert(const source: String; var s: string; StartCharIndex: PtrInt); | |
| 165 | 165 | ||
| 166 | 166 | function UTF8LowerCase(const AInStr: string; ALanguage: string=''): string; | |
| 167 | 167 | function UTF8UpperCase(const AInStr: string; ALanguage: string=''): string; | |
| 168 | 168 | function FindInvalidUTF8Character(p: PChar; Count: PtrInt; | |
| 169 | 169 | StopOnNonASCII: Boolean = false): PtrInt; | |
| 170 | 170 | function ValidUTF8String(const s: String): String; | |
| 171 | 171 | ||
| 172 | 172 | procedure AssignUTF8ListToAnsi(UTF8List, AnsiList: TStrings); | |
| 173 | 173 | ||
| 174 | 174 | //compare functions | |
| 175 | 175 | ||
| 176 | 176 | function UTF8CompareStr(const S1, S2: string): Integer; | |
| 177 | 177 | function UTF8CompareText(const S1, S2: string): Integer; | |
| 178 | 178 | ``` | |
| 179 | 179 | ||
| 180 | 180 | ### 应付目录和文件名 | |
| 181 | 181 | ||
| 182 | 182 | 辣子的控件库处理的文件名和目录名都是utf-8编码的,但RTL中的文件名和目录名都用的ansi来编码。 | |
| 183 | 183 | ||
| 184 | 184 | 举个例子,一个按钮控件,点击它来设置TFileListBox的文件夹属性为当前目录。RTL中函数[[doc:rtl/sysutils/getcurrentdir.html|GetCurrentDir]]是ansi编码的,而不是unicode,所以,转换就是必须的: | |
| 185 | 185 | ||
| 186 | 186 | ``` pascal | |
| 187 | 187 | procedure TForm1.Button1Click(Sender: TObject); | |
| 188 | 188 | begin | |
| 189 | 189 | FileListBox1.Directory:=AnsiToUTF8(GetCurrentDir); | |
| 190 | 190 | end; | |
| 191 | 191 | ``` | |
| 192 | 192 | ||
| 193 | 193 | 现在FileUtil单元定义了很多UTF8版本的文件处理函数。(译注:总结,如果想用UTF8,处理字符串请用lazutf8而不是SysUtil,处理文件和目录,使用FileUtil中的UTF8函数,而不是RTL) | |
| 194 | 194 | ||
| 195 | 195 | ``` pascal | |
| 196 | 196 | // basic functions similar to the RTL but working with UTF-8 instead of the | |
| 197 | 197 | // system encoding | |
| 198 | 198 | ||
| 199 | 199 | // AnsiToUTF8 and UTF8ToAnsi need a widestring manager under Linux, BSD, Mac OS X | |
| 200 | 200 | // but normally these OS use UTF-8 as system encoding so the widestringmanager | |
| 201 | 201 | // is not needed. | |
| 202 | 202 | function NeedRTLAnsi: boolean;// true if system encoding is not UTF-8 | |
| 203 | 203 | procedure SetNeedRTLAnsi(NewValue: boolean); | |
| 204 | 204 | function UTF8ToSys(const s: string): string;// as UTF8ToAnsi but more independent of widestringmanager | |
| 205 | 205 | function SysToUTF8(const s: string): string;// as AnsiToUTF8 but more independent of widestringmanager | |
| 206 | 206 | ||
| 207 | 207 | // file operations | |
| 208 | 208 | function FileExistsUTF8(const Filename: string): boolean; | |
| 209 | 209 | function FileAgeUTF8(const FileName: string): Longint; | |
| 210 | 210 | function DirectoryExistsUTF8(const Directory: string): Boolean; | |
| 211 | 211 | function ExpandFileNameUTF8(const FileName: string): string; | |
| 212 | 212 | function ExpandUNCFileNameUTF8(const FileName: string): string; | |
| 213 | 213 | {$IFNDEF VER2_2_0} | |
| 214 | 214 | function ExtractShortPathNameUTF8(Const FileName : String) : String; | |
| 215 | 215 | {$ENDIF} | |
| 216 | 216 | function FindFirstUTF8(const Path: string; Attr: Longint; out Rslt: TSearchRec): Longint; | |
| 217 | 217 | function FindNextUTF8(var Rslt: TSearchRec): Longint; | |
| 218 | 218 | procedure FindCloseUTF8(var F: TSearchrec); | |
| 219 | 219 | function FileSetDateUTF8(const FileName: String; Age: Longint): Longint; | |
| 220 | 220 | function FileGetAttrUTF8(const FileName: String): Longint; | |
| 221 | 221 | function FileSetAttrUTF8(const Filename: String; Attr: longint): Longint; | |
| 222 | 222 | function DeleteFileUTF8(const FileName: String): Boolean; | |
| 223 | 223 | function RenameFileUTF8(const OldName, NewName: String): Boolean; | |
| 224 | 224 | function FileSearchUTF8(const Name, DirList : String): String; | |
| 225 | 225 | function FileIsReadOnlyUTF8(const FileName: String): Boolean; | |
| 226 | 226 | function GetCurrentDirUTF8: String; | |
| 227 | 227 | function SetCurrentDirUTF8(const NewDir: String): Boolean; | |
| 228 | 228 | function CreateDirUTF8(const NewDir: String): Boolean; | |
| 229 | 229 | function RemoveDirUTF8(const Dir: String): Boolean; | |
| 230 | 230 | function ForceDirectoriesUTF8(const Dir: string): Boolean; | |
| 231 | 231 | ||
| 232 | 232 | // environment | |
| 233 | 233 | function ParamStrUTF8(Param: Integer): string; | |
| 234 | 234 | function GetEnvironmentStringUTF8(Index : Integer): String; | |
| 235 | 235 | function GetEnvironmentVariableUTF8(const EnvVar: String): String; | |
| 236 | 236 | function GetAppConfigDirUTF8(Global: Boolean): string; | |
| 237 | 237 | ``` | |
| 238 | 238 | ||
| 239 | 239 | #### Mac OS X | |
| 240 | 240 | ||
| 241 | 241 | FileUtil单元中的文件处理函数也考虑到了Mac OS X的特殊情况:OS X的normalizes filenames。例如'ä.txt'这个文件名,可以用两个不同的Unicode codepoint序列来编码(#\$C3#\$A4 and 'a'#\$CC#\$88)。在Linux和BSD下创建文件'ä.txt',文件系统存储成哪种序列都有可能。但是OS X只会使用第二种序列。这意味着: | |
| 242 | 242 | ||
| 243 | 243 | ``` pascal | |
| 244 | 244 | if Filename1 = Filename2 then ... // is not sufficient under OS X | |
| 245 | 245 | if AnsiCompareFileName(Filename1, Filename2) = 0 then ... // not sufficient under fpc 2.2.2, even not with cwstring | |
| 246 | 246 | if CompareFilenames(Filename1, Filename2) = 0 then ... // this always works (unit FileUtil or FileProcs) | |
| 247 | 247 | ``` | |
| 248 | 248 | ||
| 249 | 249 | ## UTF8和源代码文件 之 那个消失的BOM | |
| 250 | 250 | ||
| 251 | 251 | (译注:这个题目碉堡了) 你在Lazarus IDE中创建的源代码都是用UTF8编码的(译注:意味着你在代码中硬编码的字符串都是utf8编码的),不过这些文件并没有按照Windows平台的习惯去写入BOM(Byte Order Mark)。你可以在IDE的Source Editor上点击右键-\>File Settings-\>Encoding上改变这个源代码文件的编码。之所以不写入BOM是因为FPC应付Ansi String的方式。为了兼容FPC,LCL使用Ansi String,为了移植性,LCL使用UTF8的Ansi String,也就是不能带有BOM了。 因为没有写入BOM,那么例如Windows的“记事本”之类的程序可能在打开你的源代码后,ASCII之外的字符都显示成乱码,这是正常的。 例如,你在源代码中: | |
| 252 | 252 | ||
| 253 | 253 | ``` pascal | |
| 254 | 254 | Button1.Caption := 'Über'; | |
| 255 | 255 | ``` | |
| 256 | 256 | ||
| 257 | 257 | 如果没有BOM(或者编译器也没通过其他途径知道这个文件使用了什么编码),那么编译器认为源代码文件是ansi的,'Über'也是Ansi的(尽管它其实是UTF8的),而LCL号称自己也要一个Ansi(事实上是UTF8这种Ansi),'Über'就会原封不动地传给LCL(如果编译器知道这个文件使用的不是系统的Ansi,那么就会执行一个转换,转换为系统的ansi之后再传给LCL),所以一切都没有问题。 | |
| 258 | 258 | ||
| 259 | 259 | ``` pascal | |
| 260 | 260 | // source file saved as UTF without BOM | |
| 261 | 261 | if FileExists('Über.txt') then ; // wrong, because FileExists expects system encoding | |
| 262 | 262 | if FileExistsUTF8('Über.txt') then ; // correct | |
| 263 | 263 | ``` | |
| 264 | 264 | ||
| 265 | 265 | ## WideStrings和AnsiStrings | |
| 266 | 266 | ||
| 267 | 267 | 这么转换: | |
| 268 | 268 | ||
| 269 | 269 | ``` pascal | |
| 270 | 270 | var | |
| 271 | 271 | w: widestring; | |
| 272 | 272 | begin | |
| 273 | 273 | w:='Über'; // wrong, because FPC will convert from system codepage(译注:尽管其实是UTF8) to UTF16 | |
| 274 | 274 | w:=UTF8ToUTF16('Über'); // correct | |
| 275 | 275 | Button1.Caption:=UTF16ToUTF8(w); | |
| 276 | 276 | end; | |
| 277 | 277 | ``` | |
| 278 | 278 | ||
| 279 | 279 | ## 写入了BOM的源代码文件 | |
| 280 | 280 | ||
| 281 | 281 | 编译器允许不同单元使用不同的编码,所以你的某个单元可以有BOM,同时别的单元没有BOM。 | |
| 282 | 282 | ||
| 283 | 283 | ## 辣子对于Unicode应该支持成什么样子(Guidline) | |
| 284 | 284 | ||
| 285 | 285 | ### 需求 | |
| 286 | 286 | ||
| 287 | 287 | Lazarus的精神是“一次编写,到处编译”。这意味着,在理想状态下,一个支持Unicode的应用程序,应该只有一份只支持Unicode的源代码,而不用为各种不同的语言环境去定义一些编译开关之类的龌龊玩意儿。 | |
| 288 | 288 | ||
| 289 | 289 | 在LCL的外界调用接口,已经可以支援各种相容于Unicode的作业系统,让程式人员可以不用去管每个系统上面对Unicode要怎么处理的繁琐细节。 | |
| 290 | 290 | ||
| 291 | 291 | 而Lazarus本身需要注意的,则是在Lazarus内部用来沟通的字串 (例如应用程式跟LCL,以及 LCL跟视窗元件之间),都是透过Pascal的原始string (string里的每个字元都是1个Byte,而Unicode是多个Byte的字元集)。因此,逻辑上来说,Lazarus的程式码就必须以[[UTF-8]]编码来储存,才能保留住所有Unicode的相关资讯。 | |
| 292 | 292 | ||
| 293 | 293 | ### 移植到Unicode | |
| 294 | 294 | ||
| 295 | 295 | 目前绝大多数版本的Lazarus使用的是Ansi编码,因为这是Gtk1预设的编码法,也是Win32目前的预设编码法,Windows 2000以后的Windows作业系统虽然都已经能够相容于Unicode,但预设的编码法仍然是Ansi,这个情形在不久的未来恐怕会有所改变,所有的视窗元件都会支援UTF-8,而所有的应用程式在传递资料给介面时,也都需要先转换成 UTF-8了,当然,这得依赖各种IDE的作者在元件检视器里面更改程式码才能作到。 | |
| 296 | 296 | ||
| 297 | 297 | 当我们在还没完全支援Unicode的视窗元件上面开发程式的时候(例如 Gtk 2, Qt, WinCE, 或许也包含将会出现的Win32U),我们是使用IDE来对比较稳定的视窗元件进行编译的 (例如Gtk跟Win32)。为了保持一致性(例如以ISO字元编码把资料传递给UTF-8的视窗元件),让IDE跟视窗元件使用一致的编码是必要的,这也就表示在能够制作出Unicode的应用程式前,我们将会需要一个稳定的UTF-8的IDE程式。 | |
| 298 | 298 | ||
| 299 | 299 | 目前我们有几组不同的视觉元件,分别使用以下的编码法: | |
| 300 | 300 | ||
| 301 | 301 | - 使用ANSI编码法: win32跟 gtk (1) 介面 | |
| 302 | 302 | ||
| 303 | 303 | - 使用 UTF-8 编码法: gtk (1), gtk2, qt, fpGUI, carbin | |
| 304 | 304 | ||
| 305 | 305 | - 目前还使用ANSI编码,但需要升级到UTF-8编码: win32, wince | |
| 306 | 306 | ||
| 307 | 307 | 请留意,gtk 1同时属于ANSI跟UTF-8的阵营喔,这是因为gtk 1的编码法,是可以从Gtk 1的环境变数里面加以控制的。 | |
| 308 | 308 | ||
| 309 | 309 | 正如目前的Lazarus一样,大多数的应用程式目前都能正常运作,如果用win32, wince或gtk介面重新编译,就得面对要编译其他视窗元件时,使用不同编码的窘境了。而支援UTF-8的应用程式在重新编译给使用Unicode的视窗元件时,就没有这个问题。 | |
| 310 | 310 | ||
| 311 | 311 | 很重要的一点是,当您要编译程式时,请记得使用跟您要编译的程式相同编码法的IDE来作。这是因为IDE在进行程式编译的时候,IDE是用它被编译时的编码法来产生LFM跟LRS档案的,而不是我们想要什么编码法,它就能自动切换过去的,这点非常重要,不可不察。 | |
| 312 | 312 | ||
| 313 | 313 | ## 发展路线 | |
| 314 | 314 | ||
| 315 | 315 | 目前我们已经有了准则,所以该建立发展路线,并加以实现的时候了。 为此,我们建立了以下的计划,我们的计划是把工作分为两个群组,一个是主要工作,另一个是次要工作。 | |
| 316 | 316 | ||
| 317 | 317 | 所有的主要工作都必须在我们宣布Lazarus支援之前完成,这些工作会被当成我们工作中的主要确认部分。 | |
| 318 | 318 | ||
| 319 | 319 | 次要工作则是该作,但没有自愿者想作,或者为这些工作定出范围之前不会进行的。 | |
| 320 | 320 | ||
| 321 | 321 | ### 主要工作 | |
| 322 | 322 | ||
| 323 | 323 | **使 Win32 视窗元件支援 UTF-8** | |
| 324 | 324 | ||
| 325 | 325 | 备注: 在这个步骤中,我们会将所有的32 bits Windows作业系统同时当成目标,这阶段中所有写出来的程式码都会在目前的win32介面中用IFDEF来区隔,以避免在主要的介面中产生问题。在过渡时期结束之后,IFDEF的宣告就会全部移除,只留下Unicode的支援。 | |
| 326 | 326 | ||
| 327 | 327 | 状态: 部分已完成。 | |
| 328 | 328 | ||
| 329 | 329 | **更新 Gtk 2 的键盘程式码,使得UTF-8能够被支援** | |
| 330 | 330 | ||
| 331 | 331 | 备注: | |
| 332 | 332 | ||
| 333 | 333 | 状态: 几乎已完成。部分gtk2预先定义的功能,让使用者自订的部分还没有完成,但我不知道哪几个语系会使用者这些功能。 | |
| 334 | 334 | ||
| 335 | 335 | **让Lazarus IDE能正确的跟Win32 Unicode视窗元件运作并支援UTF-8** | |
| 336 | 336 | ||
| 337 | 337 | 备注: | |
| 338 | 338 | ||
| 339 | 339 | 状态: 已完成。除了字元对应表,目前字元对应表仍旧只显示255个字元,但反正目前所有的OS都已经提供了很好的Unicode字元对应表,所以这应该也不是那么重要了。 | |
| 340 | 340 | ||
| 341 | 341 | **让Lazarus IDE能正确的跟Gtk 2视窗元件运作并支援UTF-8** | |
| 342 | 342 | ||
| 343 | 343 | 备注: | |
| 344 | 344 | ||
| 345 | 345 | 状态: 已完成。还有些gtk2介面的问题,但这已经跟UTF-8无关了 | |
| 346 | 346 | ||
| 347 | 347 | ### 次要工作 | |
| 348 | 348 | ||
| 349 | 349 | **升级Windows CE的视窗元件,使它能使用UTF-8** | |
| 350 | 350 | ||
| 351 | 351 | 备注: 字串转换的程式码已经集中在winceproc.pp这个档案里面,还需要许多测试。 | |
| 352 | 352 | ||
| 353 | 353 | 状态: 尚未开始 | |
| 354 | 354 | ||
| 355 | 355 | **升级Gtk 1键盘功能,让它能使用UTF-8** | |
| 356 | 356 | ||
| 357 | 357 | 备注: | |
| 358 | 358 | ||
| 359 | 359 | 状态: 尚未开始 | |
| 360 | 360 | ||
| 361 | 361 | **完成synedit对由右到左(RTL)的文字显示的支援** | |
| 362 | 362 | ||
| 363 | 363 | 备注: RTL是指由右到左的输入法,例如阿拉伯文。 | |
| 364 | 364 | ||
| 365 | 365 | 状态: 尚未开始 | |
| 366 | 366 | ||
| 367 | 367 | ## Unicode 须知 | |
| 368 | 368 | ||
| 369 | 369 | Unicode的标准是将整数的0到10FFFF(十六进位)对应为文字。每一个对应关系,称为一个个的编码点(code point)。换句话说,Unicode的字元原则上是定义了U+000000到U+10FFFF个编码点(用十进位来算,是 0到1,114,111)。 | |
| 370 | 370 | ||
| 371 | 371 | 要表现Unicode的编码点的位元顺序,一共有三种方法。这些方法被称为Unicode转换格式(Unicode transformation formats)分别是: UTF-8, UTF-16和UTF-32。这三种格式之间是可以相互转换的,以下是这些格式的基本说明: | |
| 372 | 372 | ||
| 373 | 373 | (原文) | |
| 374 | 374 | ||
| 375 | - | ||
| 376 | - | ||
| 377 | - | ||
| 378 | - | ||
| 379 | - | ||
| 380 | - | ||
| 375 | + | ``` pascal | |
| 376 | + | UTF-8 UTF-16 UTF-32 | |
| 377 | + | Smallest code point [hex] 000000 000000 000000 | |
| 378 | + | Largest code point [hex] 10FFFF 10FFFF 10FFFF | |
| 379 | + | Code unit size [bits] 8 16 32 | |
| 380 | + | Minimal bytes/character 1 2 4 | |
| 381 | + | Maximal bytes/character 4 4 4 | |
| 382 | + | ``` | |
| 381 | 383 | ||
| 382 | 384 | (中文) | |
| 383 | 385 | ||
| 384 | - | ||
| 385 | - | ||
| 386 | - | ||
| 387 | - | ||
| 388 | - | ||
| 389 | - | ||
| 386 | + | ```text | |
| 387 | + | UTF-8 UTF-16 UTF-32 | |
| 388 | + | 最小编码点 [十六进位] 000000 000000 000000 | |
| 389 | + | 最大编码点 [十六进位] 10FFFF 10FFFF 10FFFF | |
| 390 | + | 单位编码Size [bits] 8 16 32 | |
| 391 | + | 占用位元组量(最少) 1 2 4 | |
| 392 | + | 占用位元组量(最多) 4 4 4 | |
| 393 | + | ``` | |
| 390 | 394 | ||
| 391 | 395 | **UTF-8** 包含几个重要且有用的属性:它是以Byte的顺序进行解译的,所以没有Hi-Byte跟Lo-Byte的差别(其它双位元组的多国语系字元编码都有这样的问题)。 Unicode对字元的定义中,从U+0000到U+007F (ASCII)正好就是直接对应到00h到7Fh,可以跟ASCII直接相容。这意味着使用7-bit ASCII字元的档案或字串,在传递ASCII跟UTF-8的时候,是完全相同的编码方式。而编码点大于U+007F的字元则是依照位元组的顺序进行编码,正好每两个Byte就能代表一个Unicode的字元。因此不会出现一个字元的Byte使用或涵盖到别的字元的资料,也使得制作子字串的搜寻功能简单多了。代表非ASCII字元的位元组中,第一个Byte的内容一定必须在C0h到FDh之间,并且说明这个Unicode字元是使用了几个Bytes来记录的。所有在第一个Byte之后的资料,都一定落在80h到BFh之间,这样的规则也使得自动化与重新修复文件的程序变得更简单。 | |
| 392 | 396 | ||
| 393 | 397 | **UTF-16**则包含了以下重要的属性: 它只使用16 bit的Word对从U+0000到U+d7ff这些字元进行编码,而其余的Unicode字元编码,则会使用成对的16-bit Words。 | |
| 394 | 398 | ||
| 395 | 399 | 最后,任何一个Unicode字元都可以用32-bit为单位的资料来表现,就称为**UTF-32**. | |
| 396 | 400 | ||
| 397 | 401 | 如果您需要更多的资料,请参阅: [Unicode FAQ - Basic questions](http://www.unicode.org/faq/basic_q.html), [Unicode FAQ - UTF-8, UTF-16, UTF-32 & BOM](http://www.unicode.org/faq/utf_bom.html), [Wikipedia: UTF-8](http://en.wikipedia.org/wiki/UTF-8) [1](http://en.wikipedia.org/wiki/ISO-8859) | |
| 398 | 402 | ||
| 399 | 403 | ## Lazarus 元件库架构须知 | |
| 400 | 404 | ||
| 401 | 405 | LCL包含了两个部分: | |
| 402 | 406 | ||
| 403 | 407 | 1. 跟编译目标作业平台无关的部分,这部分是使用跟Delphi VCL相似的类别架构来实现的。 | |
| 404 | 408 | 2. "Interfaces" – 使用各编译目标作业平台相关的API来实现的。 | |
| 405 | 409 | ||
| 406 | 410 | 介于两个部分之间的沟通,则是透过TWidgetset这个抽象类别来达成的,每个Widgetset的实现都是从TWidgetset这个父类别衍生而来的。 | |
| 407 | 411 | ||
| 408 | 412 | GTK 1的视觉元件是最旧的版本。在该版本的视觉元件当中,字元的编码是以”LANG”这个环境变数来决定的,通常是” ISO-8859-n”这一类的单位元字串编码。近几年内建GTK 1的系统,已经开始把预设字元编码设定为UTF-8了,例如2007年的Mandriva就是一例。在Lazarus的Gtk 1介面中,还少了支援UTF-8的键盘控制功能,这是个大问题,如果不解决的话,Lazarus将无法真正支援跨平台Unicode相容的目标。 | |
| 409 | 413 | ||
| 410 | 414 | Gtk2的视觉元件只能使用UTF-8编码,并且完全支援UTF-8的各项要求。 | |
| 411 | 415 | ||
| 412 | 416 | Win32介面在预设时,使用的是ANSI编码的视觉元件,目前已经开始进行修改,让它能够支援UTF-8,但因为还没完成,所以预设是不使用UTF-8的,也因此目前在Win32介面的视觉元件上,暂时还无法使用Unicode。 | |
| 413 | 417 | ||
| 414 | 418 | Qt介面已经完成了支援UTF-8的准备,在Qt介面中,原生的字元编码是使用UTF-16,但Lazarus的Qt介面会把UTF-8转换为UTF-16,所以在支援上没有问题。 | |
| 415 | 419 | ||
| 416 | 420 | Windows CE只支援UTF-16的字元编码,但Lazarus的Windows CE介面则是在呼叫Windows API之前,先把ISO字元转换为UTF-16编码,所以这部分还算容易修改,就像目前我们把所有的字元转换函式集中放在winceproc.pp里面一样。 | |
| 417 | 421 | ||
| 418 | 422 | 如果您需要更多资讯,请参考: [[LCL Internals|LCL内部资讯]] | |
| 419 | 423 | ||
| 420 | 424 | ## 让win32介面相容于Unicode | |
| 421 | 425 | ||
| 422 | 426 | ### 编译能使用Unicode的LCL-Win32函式库 | |
| 423 | 427 | ||
| 424 | 428 | 要使Windows版的LCL函式库能使用Unicode,您得先到Lazarus的选单中"Tools" --\> "Configure Build Lazarus"进行设定。 请在"Options"的栏位中加上” –dWindowsUnicodeSupport”这个设定值,并把所有的建置对象都选为NONE,只留下LCL的设定选项是Clean+Build,然后再设定win32为要建置的视觉元件(widgetset),按下”Build”按键,即可将LCL重新编译为与Unicode相容的版本了。 完成后,您就可以把您已完成的应用程式重新编译,编译完成后,它们也都能够支援Unicode了。 | |
| 425 | 429 | ||
| 426 | - | ||
| 427 | - | ||
| 428 | - | ||
| 430 | + | ```text | |
| 431 | + | Note: Since Lazarus version 0.9.25 revision 14883 this operation is not | |
| 432 | + | needed anymore as Lazarus is unicode enabled by default. | |
| 433 | + | 注意: 自Lazarus 0.9.25 14883版本后,这些操作已经不需要了。因为Lazarus已经默认支持unicode(好消息!!)。 | |
| 434 | + | ``` | |
| 429 | 435 | ||
| 430 | 436 | ### 准则 | |
| 431 | 437 | ||
| 432 | 438 | 首先,也是最重要的,所有为Win32介面进行的增补工作,都必须被包在 IFDEF WindowsUnicodeSupport这个编译条件式里面,以避免破坏了现有的ANSI介面,等到Unicode相容修正的专案稳定之后,这些IFDEF的编译条件式就会一起被拿掉,而只留下Unicode相容的程式码。在目前这个时间点上,所有现存使用ANSI标准编码的程式,都还得由程式设计人员将之升级,才能与Unicode相容。 | |
| 433 | 439 | ||
| 434 | 440 | Windows平台 \<= Win9x只支援ISO系列的字元编码标准,并只有部分功能支援Unicode。Windows系列的平台,是从Windows NT跟Windows CE开始完全支援Unicode的(也同时还支援ISO系列编码,算是双轨并行),Win9x跟NT的API里面,每一个功能都同时提供了两个函式,一个是ANSI编码的(函式名称结尾都会加个A),另一个则是Unicode相容的(函式名称结尾则是会加个W)。 | |
| 435 | 441 | ||
| 436 | 442 | - W的函式中如果需要传递字串参数,接受的字串必须是WideString,例如UTF-16字串,而Windows CE只使用 *W的API。 | |
| 437 | 443 | ||
| 438 | 444 | #### 在Windows 9x上面,Unicode系列函式的呈现 | |
| 439 | 445 | ||
| 440 | 446 | 有些Unicode系列的API也会呈现在Windows 9x平台上,以下就是这些Unicode系列API的列表: <http://msdn.microsoft.com/library/default.asp?url=/library/en-us/mslu/winprog/other_existing_unicode_support.asp> | |
| 441 | 447 | ||
| 442 | 448 | 转换范例: | |
| 443 | 449 | ||
| 444 | 450 | GetTextExtentPoint32(hdcNewBitmap, LPSTR(ButtonCaption), | |
| 445 | 451 | Length(ButtonCaption), TextSize); | |
| 446 | 452 | ||
| 447 | 453 | 要改为: | |
| 448 | 454 | ||
| 449 | 455 | {$ifdef WindowsUnicodeSupport} | |
| 450 | 456 | GetTextExtentPoint32W(hdcNewBitmap, PWideChar(Utf8Decode(ButtonCaption)), Length(WideCaption), TextSize); | |
| 451 | 457 | {$else} | |
| 452 | 458 | GetTextExtentPoint32(hdcNewBitmap, LPSTR(ButtonCaption), Length(ButtonCaption), TextSize); | |
| 453 | 459 | {$endif} | |
| 454 | 460 | ||
| 455 | 461 | #### 需要转换ANSI跟Unicode版本的函式 | |
| 456 | 462 | ||
| 457 | 463 | 第一个简单的转换范例: | |
| 458 | 464 | ||
| 459 | 465 | function TGDIWindow.GetTitle: String; | |
| 460 | 466 | var | |
| 461 | 467 | l: Integer; | |
| 462 | 468 | begin | |
| 463 | 469 | l := Windows.GetWindowTextLength(Handle); | |
| 464 | 470 | SetLength(Result, l); | |
| 465 | 471 | Windows.GetWindowText(Handle, @Result[1], l); | |
| 466 | 472 | end; | |
| 467 | 473 | ||
| 468 | 474 | 必须转换为: | |
| 469 | 475 | ||
| 470 | 476 | function TGDIWindow.GetTitle: String; | |
| 471 | 477 | var | |
| 472 | 478 | l: Integer; | |
| 473 | 479 | AnsiBuffer: string; | |
| 474 | 480 | WideBuffer: WideString; | |
| 475 | 481 | begin | |
| 476 | 482 | ||
| 477 | 483 | {$ifdef WindowsUnicodeSupport} | |
| 478 | 484 | ||
| 479 | 485 | if UnicodeEnabledOS then | |
| 480 | 486 | begin | |
| 481 | 487 | l := Windows.GetWindowTextLengthW(Handle); | |
| 482 | 488 | SetLength(WideBuffer, l); | |
| 483 | 489 | l := Windows.GetWindowTextW(Handle, @WideBuffer[1], l); | |
| 484 | 490 | SetLength(WideBuffer, l); | |
| 485 | 491 | Result := Utf8Encode(WideBuffer); | |
| 486 | 492 | end | |
| 487 | 493 | else | |
| 488 | 494 | begin | |
| 489 | 495 | l := Windows.GetWindowTextLength(Handle); | |
| 490 | 496 | SetLength(AnsiBuffer, l); | |
| 491 | 497 | l := Windows.GetWindowText(Handle, @AnsiBuffer[1], l); | |
| 492 | 498 | SetLength(AnsiBuffer, l); | |
| 493 | 499 | Result := AnsiToUtf8(AnsiBuffer); | |
| 494 | 500 | end; | |
| 495 | 501 | ||
| 496 | 502 | {$else} | |
| 497 | 503 | ||
| 498 | 504 | l := Windows.GetWindowTextLength(Handle); | |
| 499 | 505 | SetLength(Result, l); | |
| 500 | 506 | Windows.GetWindowText(Handle, @Result[1], l); | |
| 501 | 507 | ||
| 502 | 508 | {$endif} | |
| 503 | 509 | ||
| 504 | 510 | end; | |
| 505 | 511 | ||
| 506 | 512 | ### Roadmap 未来发展计划 | |
| 507 | 513 | ||
| 508 | 514 | #### 在相容于Unicode的延伸计划中,什么是必须要作的: | |
| 509 | 515 | ||
| 510 | 516 | - TForm, TButton, TLabel | |
| 511 | 517 | - 大多数的控制项 | |
| 512 | 518 | - 选单元件 | |
| 513 | 519 | - LCLIntf.ExtTextOut 以及大多数和字串相关的WinAPI | |
| 514 | 520 | - 以TStrings为基础的控制项. 例如: TComboBox, TListBox等等 | |
| 515 | 521 | - SynEdit 显示与输入UTF-8字元必须正确 | |
| 516 | 522 | ||
| 517 | 523 | #### 要支援Unicode的话,目前已知的问题: | |
| 518 | 524 | ||
| 519 | 525 | - SynEdit不支援由右到左显示的字元(RTL) | |
| 520 | 526 | ||
| 521 | 527 | - Is OpenFileDialogCallBack tested with selection large numbers of files? | |
| 522 | 528 | - Is this problem unicode specific? I think it's a generic problem. --Sekelsenmat 13:40, 14 February 2008 (CET) | |
| 523 | 529 | - Maybe. I know I tested it with large number of files before the Unicode version was added. If it is a generic problem, then the the non-Unicode version got broken, when the Unicode version was added. Vincent 21:45, 15 February 2008 (CET) | |
| 524 | 530 | - Associated bugtracker item: <http://bugs.freepascal.org/view.php?id=10918> Fixed and implemented. | |
| 525 | 531 | - class function TWin32WSSelectDirectoryDialog.CreateHandle: Title, FileName and InitialDir should be made Unicode aware. | |
| 526 | 532 | - Associated bugtracker item: <http://bugs.freepascal.org/view.php?id=10919> Implemented. | |
| 527 | 533 | - 在编辑器上面双击非ANSI编码的字元时,被双击的字不会被选取,反而是被双击的字左方的其他字会被选取起来 | |
| 528 | 534 | - 复制贴上Unicode字元的时候,如果当时的视窗环境不是使用Unicode为编码字元的话,复制贴上的动作会不正确 | |
| 529 | 535 | - MessageBox上面的按键文字就算已经翻译完成,也无法正确显示Unicode字元。这已经在IDE上面测试过了,不过也可能单纯的就只是IDE的问题而已。 | |
| 530 | 536 | - 在Project option设定应用程式Title的时候,如果设定为Unicode的字串,显示可能不正确。 | |
| 531 | 537 | ||
| 532 | 538 | 在重新检视程式码之后,下列的问题需要进行测试,因为这些程式码似乎无法相容于Unicode: | |
| 533 | 539 | ||
| 534 | 540 | - 在PrepareCreateWindow (Win32WSControls这个单元档里面) 的这行程式: | |
| 535 | 541 | ||
| 536 | - | ||
| 542 | + | ``` pascal | |
| 543 | + | StrCaption := PChar(AWinControl.Caption); | |
| 544 | + | ``` | |
| 537 | 545 | ||
| 538 | 546 | - (还有一些问题是没有被确认的,如果经过确认的话,就会一道列在上述的清单里面) | |
| 539 | 547 | ||
| 540 | 548 | ### 荧幕截图 | |
| 541 | 549 | ||
| 542 | 550 | 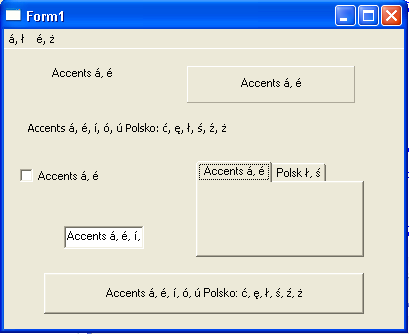 | |
| 543 | 551 | ||
| 544 | 552 | ## 额外参考 | |
| 545 | 553 | ||
| 546 | 554 | - [[UTF-8]] - Description of UTF-8 strings | |
| 547 | 555 | ||
| 548 | 556 | --- | |
| 549 | 557 | *From the Free Pascal wiki, page "LCL Unicode Support/zh CN", as it stood on 2020-02-19 after a change by Trev, out of the wiki's dump of 2024-05-26. Copyright stays with the author who wrote it, according to the old wiki's [[Licensing]] page. If you have concerns about this material, [message the admin](/wiki-contact).* |